


Editing talking-head videos is rarely slow because of the cutting. The real time sink is finding visuals: a sentence describes an abstract idea, and the stock library has nothing that matches. Someone turned this into an open-source Skill called gbro-collage-broll. You give it a talking-head line of about 5 seconds, and it first comes up with a visual metaphor, then builds it into a halftone paper-collage assembly animation.
Below are the examples the project published itself:


Images come from the project repository README.
What it produces
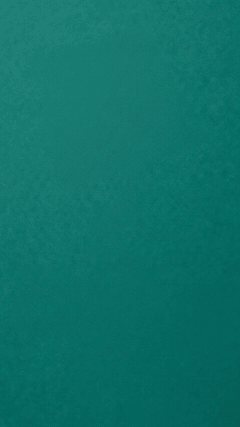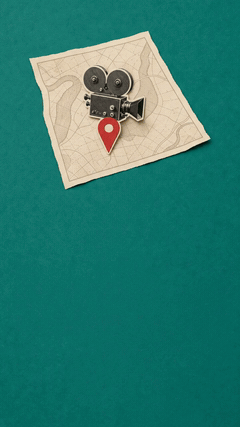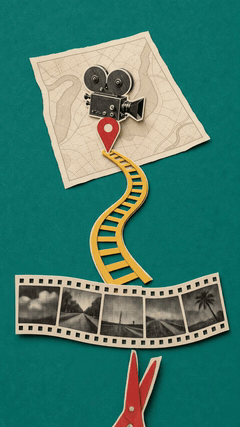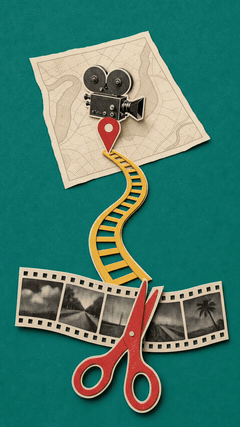
- The frame is a flat, solid-colored paper surface with black-and-white halftone photo cutouts on it, plus a few colored cardstock pieces.
- The pieces start from an empty frame and slide in one by one until they lock into place, with the texture of stop-motion animation. It is not a fade-in plus a slow push.
- Default output: vertical 9:16, 5 seconds, 720×1280, no sound, placed directly under the talking head.

The smartest design: three checkpoints
The core of this Skill is not a prompt but three mandatory checkpoints:
Sign in to unlock this key section
New accounts get 10 free credits, plus 1 more for each daily check-in. Spend 1 credit to unlock and it stays open for you.
The author's reasoning is practical: changing text costs nothing, regenerating an image is cheap, rerunning a video is expensive. So your attention goes to aesthetic judgment, and the paid steps come last. In batch mode, only the items you approve move on to the next step.
Check the prerequisites first
This is not a one-click tool that works right after installation. Know these first:
- Static frames rely on Codex's built-in image generation. In other agents, you need to prepare an equivalent image generation method yourself, or provide the static images directly.
- Video uses your own Gemini key, billed per usage. Costs are borne by the Google account tied to that key; the exact prices are whatever Google officially states.
- Requires ffmpeg and Python 3.10 or above. Used for processing first and last frames, removing the audio track and producing check images.
- On first use, the Skill runs a self-check first and tells you what is missing.
Installation and technical details are all on the Skill page. Just hand it to your agent: Talking-head B-roll paper-collage animation.
Walkthrough: from one spoken line to a finished clip
Step 1: Give it one line
Say to your agent:
collage b-roll: Many people think AI is here to think for you. In fact it is more like a mirror, reflecting the gaps in your question.
Other trigger phrases include "paper-collage b-roll", "halftone collage" and "collage-style visuals for a clip." You can also give several lines at once: one metaphor and one finished clip per line.
Step 2: First checkpoint, review the metaphor only
For each item you get its core meaning, mood, a one-sentence visual proposition, 3 to 6 key objects, background color and assembly order. This step is text only, so don't rush to approve. Ask yourself three things:
- Can a viewer understand the sentence at a glance from the picture?
- Are there too many objects? Too many weakens the meaning and makes the animation unstable.
- Does the background color fit the meaning?
If you're not satisfied, just say "swap the mirror for...". Changing text costs nothing.
Step 3: Second checkpoint, review the static frames
Once the metaphor passes, the final static frames and an overview image are produced. Focus on:
- Is the metaphor clear and is the subject focused?
- Does the picture contain any fake text, logos or watermarks?
- Is there enough empty solid space (because the animation assembles from empty space)?
- Are the elements 3 to 6 clear large groups rather than a screen full of fragments?
If you're not satisfied, ask it to regenerate just this one. The old overview image is kept so you can compare.
Step 4: Third checkpoint, generate the video
After the static frame passes, the Skill automatically makes the video from first and last frames: the first frame is the same-colored empty paper surface, the last frame is the static frame you confirmed, and the model fills in the middle with pieces sliding in and locking into position. Afterward it extracts frames every second for checking and places the final frame side by side with your confirmed static frame for comparison.
Step 5: Watch it yourself once more
- Is the first frame close to an empty frame?
- In the middle, do the pieces really enter one by one, rather than the whole thing fading in?
- Are there any cuts, sudden zooms or distortions?
- Does the last frame drift away from the confirmed static frame?
Slight pose changes that don't affect the meaning count as passing. Don't rerun for them, since reruns cost money.
Pitfalls to avoid
- A bit of paper shows at the edge of the first frame: Minor issues are acceptable; if you need a strictly empty opening, consider using an animation tool with an editable timeline to fix the early part.
- Weak sense of assembly: Reduce the number of elements and change the motion to an explicit "slide in piece by piece and lock."
- Fake text appears: Regenerate from the static frame instead of hoping the video stage fixes it.
- Need precise control over layers or shots: This Skill is not suitable. It does not split transparent layers and has no editable timeline.
- Want a real person on camera or a product ad: Don't use it for that.
- Key security: Keep the key only in environment variables, don't share it with anyone, and don't write it into files.
If you don't want to pay for video
The author demonstrated on social media that you can call an image model through Codex to output a GIF directly, without running any video model at all. That is the author's claim; we have not verified it, and the repository still defaults to Omni Flash for first-and-last-frame video. You can go through only the first two checkpoints, use the static frame as a single still illustration, and decide whether to generate video once you are satisfied.
Want your agent to do it directly? Hand it Talking-head B-roll paper-collage animation.
References
- gbro-collage-broll, MIT license
Comments (0)
No comments yet. Start the conversation.